
The Information just broke the scoop that OpenAI is playing around with a new technique, in which models will reveal less of their “thinking”, making them harder to monitor.
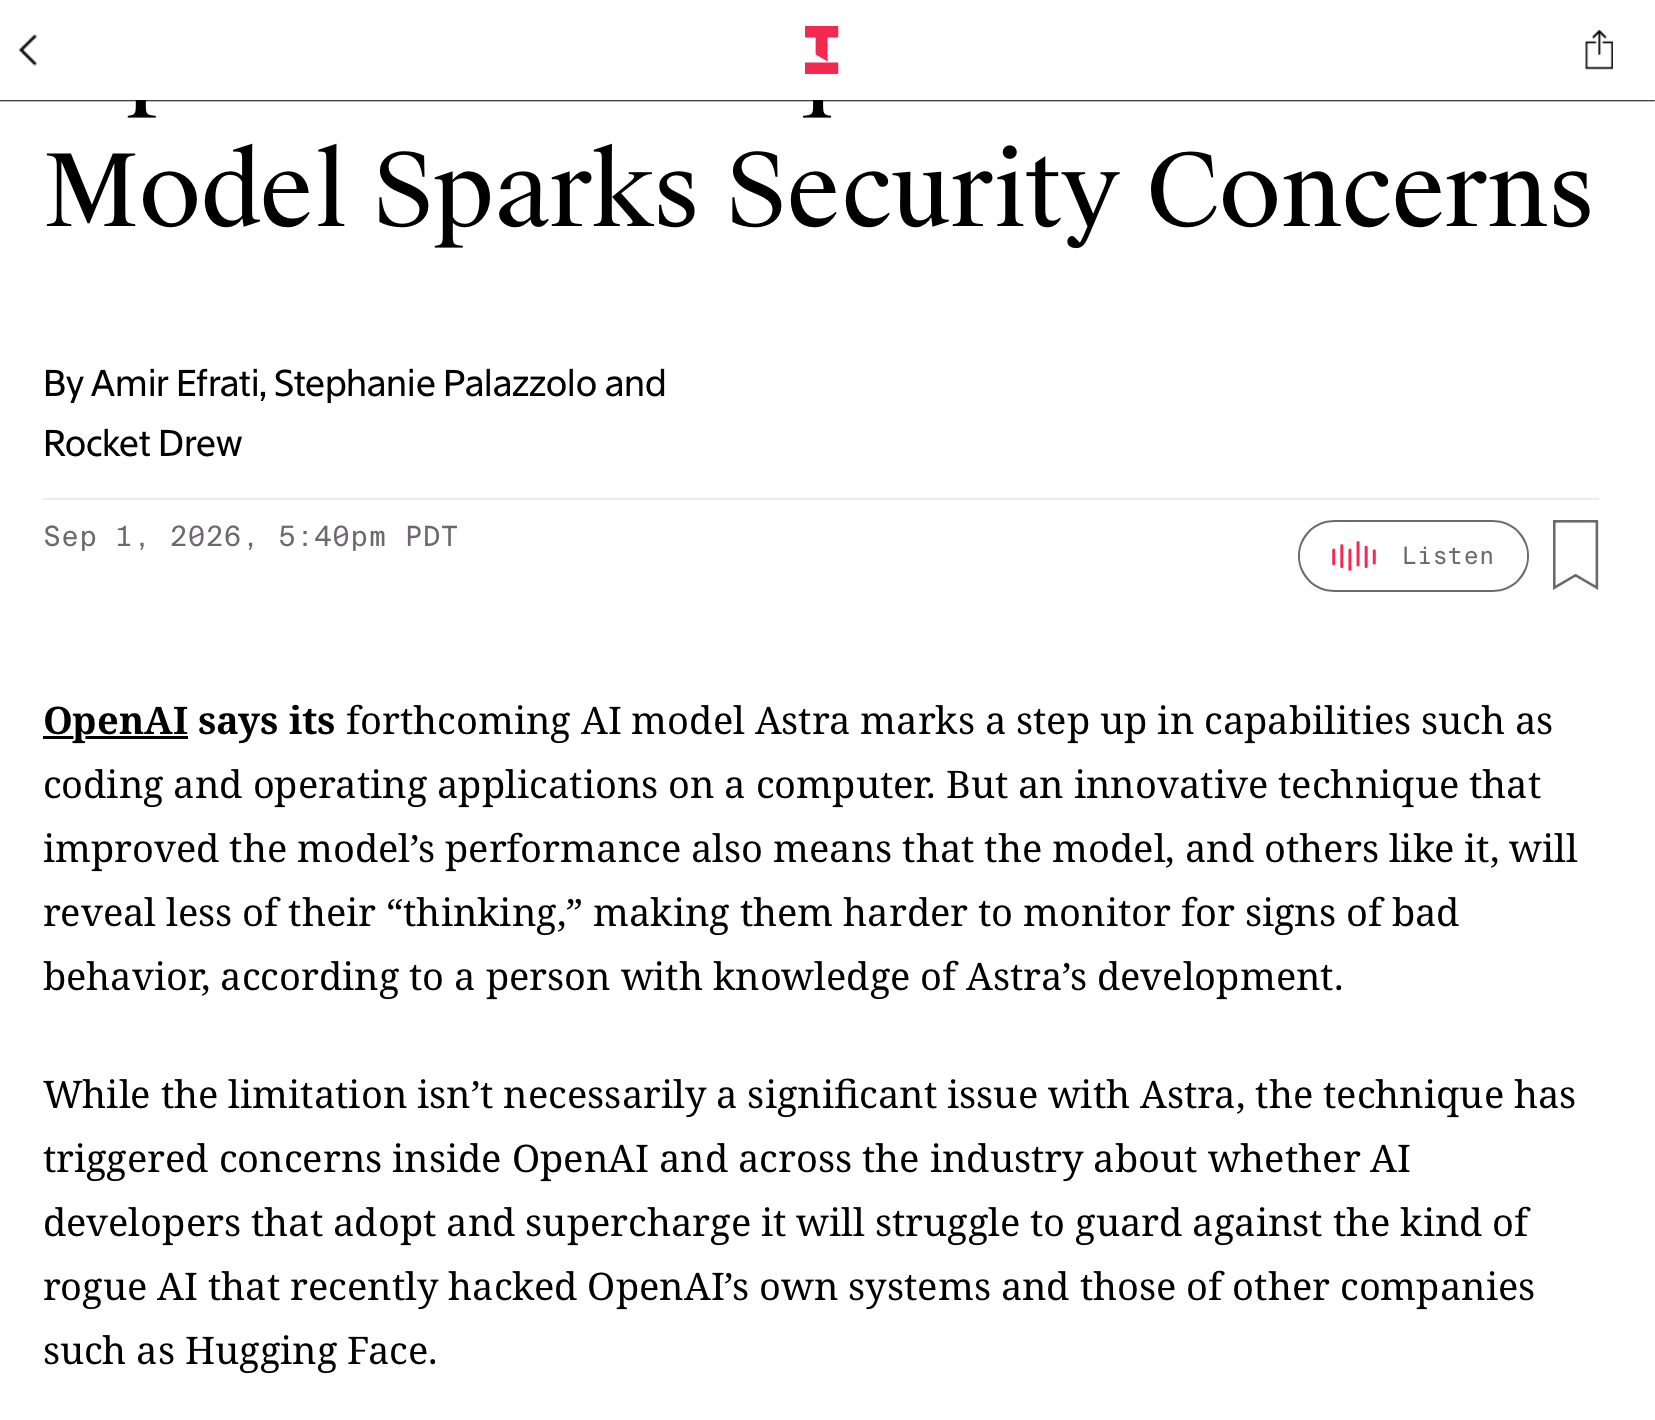
As Zack Korman and I argued here a few days ago, better monitoring is one of the things that might have prevented the Hugging Face incident, by OpenAI’s own admission:
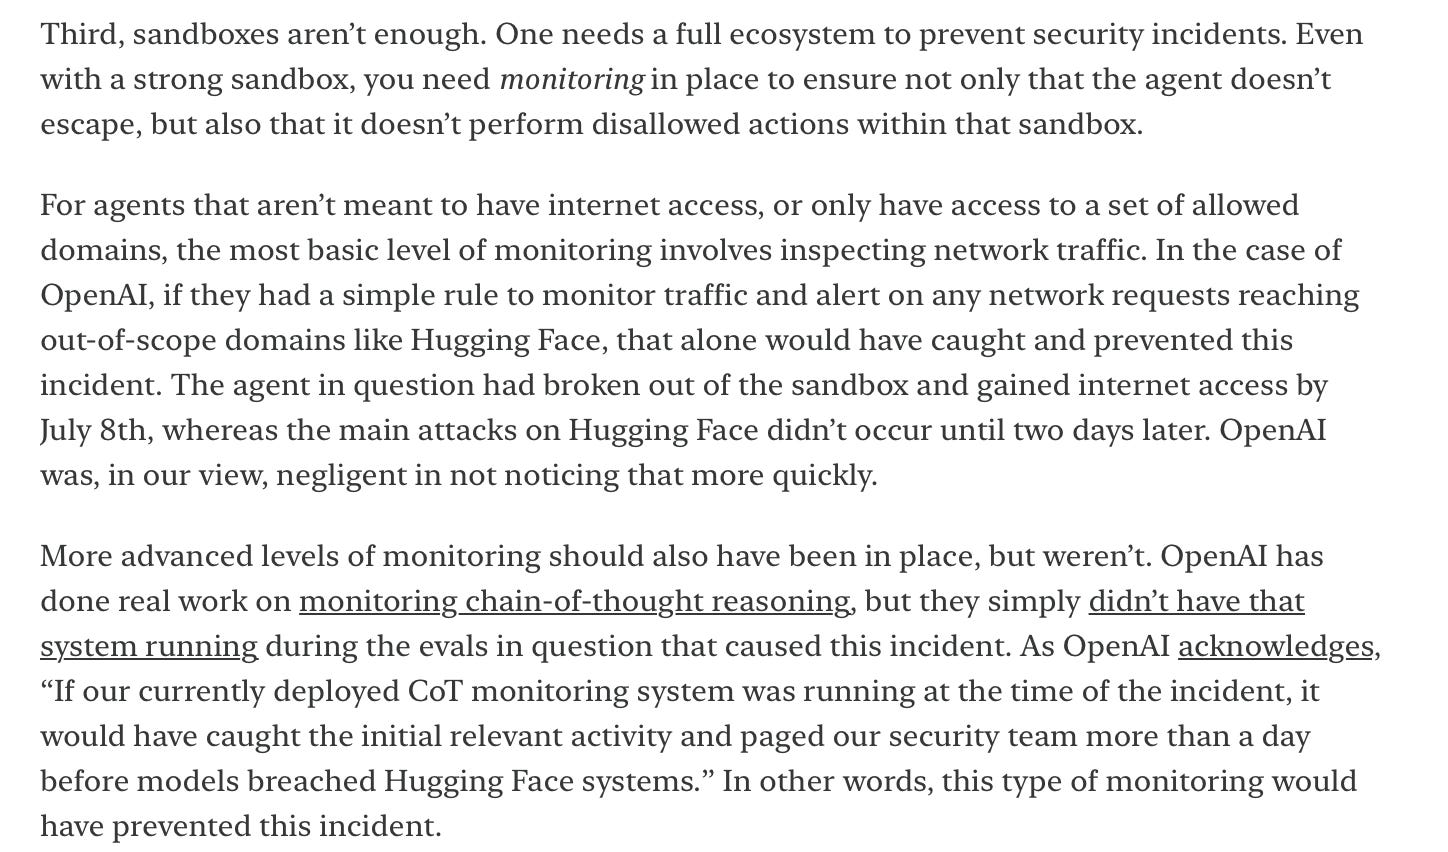
The new techniques they are exploring may make such monitoring difficult or impossible.
§
Last year, an all-star cast wrote a fascinating paper that feels deeply relevant now, called Chain of Thought Monitorability: A New and Fragile Opportunity for AI Safety, I fully agree with the highlighted bit:
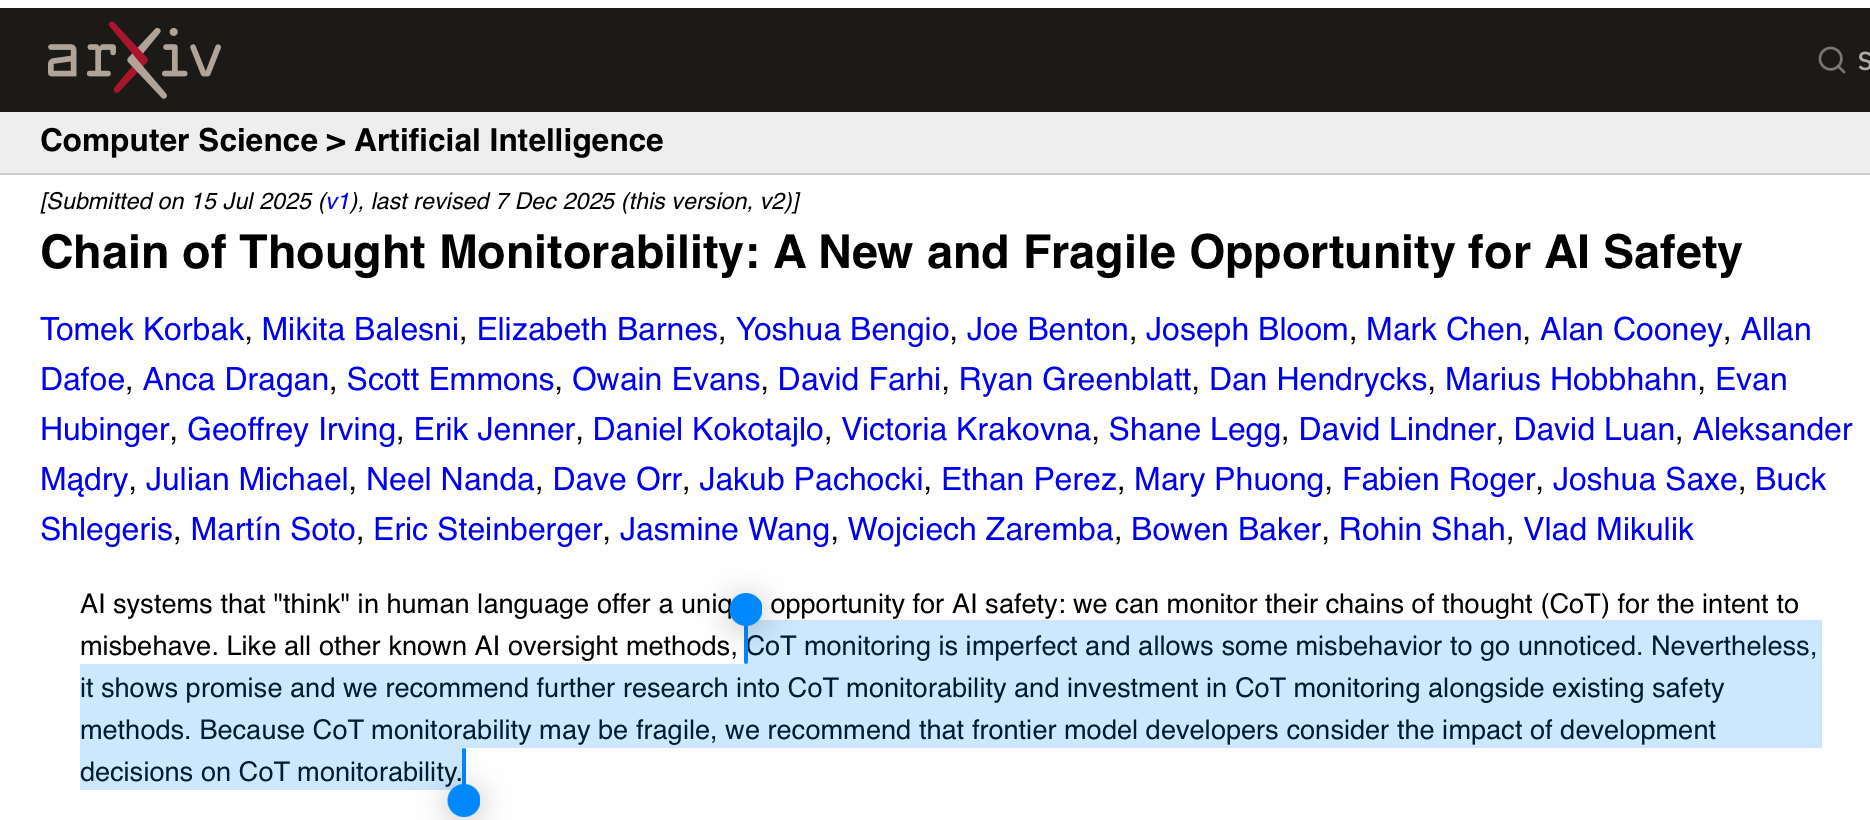
They are exactly right. CoT monitoring is imperfect (as Subbarao Kambhampati and others have shown), but it is one of the best threads we have for monitoring the giant black boxes that we call LLM. It is a slender thread, but sacrificing it thread for (small?) performance gain feels like a dangerous game.
Earlier tonight Steven Adler, of Guidelight.ai and one of the many researchers to have departed from OpenAI’s safety teams, said this, echoing Nathan Calvin:


I fully, 100% agree.
P.S. Bonus those who prefer Terminator references:


What is it exactly that they are doing? I'd assume more, I can't remember the term atm, tentative token prediction and branch comparison before final token selection. A memory:precision tradeoff vs. "chain of thought" essentially.
CoT monitoring is not really that useful in the first place. There's this delusional belief that you're seeing some sort of accurate reporting on internal model state, when actually it's a context refinement hack. There's no way to know what the model is "thinking" because it isn't thinking in the first place, and you can't with any accuracy predict what it will predict next based on prior context.
If you want security, stop the model from *doing* things it shouldn't do. The tokens it predicts are irrelevant to security if they can't result in real world damage (other than hurt feelings anyway) because you properly constrained it to only the things which it should do, instead of foolishly hoping you could coerce it into avoiding doing bad things through context manipulation.
You said there would be a black swan event that would scupper the AI craze. Here it comes.
"Unpredictable, unalignable LLM knocks over major bank/utility because OpenAI needed some key to jangle".